- AI implementation means changing how a process runs, not buying a licence.
- Our five steps: map the work, build the company brain, build a pipeline (not a chatbot), keep people in the approval seat, then measure and widen.
- The company brain is your business written down as small cards (DNA, rules, data) so agents load only what a task needs.
- The best first candidates are high-volume, text-heavy, rule-bound processes where a person checks the result anyway.
- We run the same model inside Saigon Digital: the AI drafts, people send.
AI implementation is the work of putting AI inside the processes a business already runs, so the work gets done faster and more reliably while people stay accountable for the result. In our experience it succeeds or fails on what happens before anyone chooses a model.
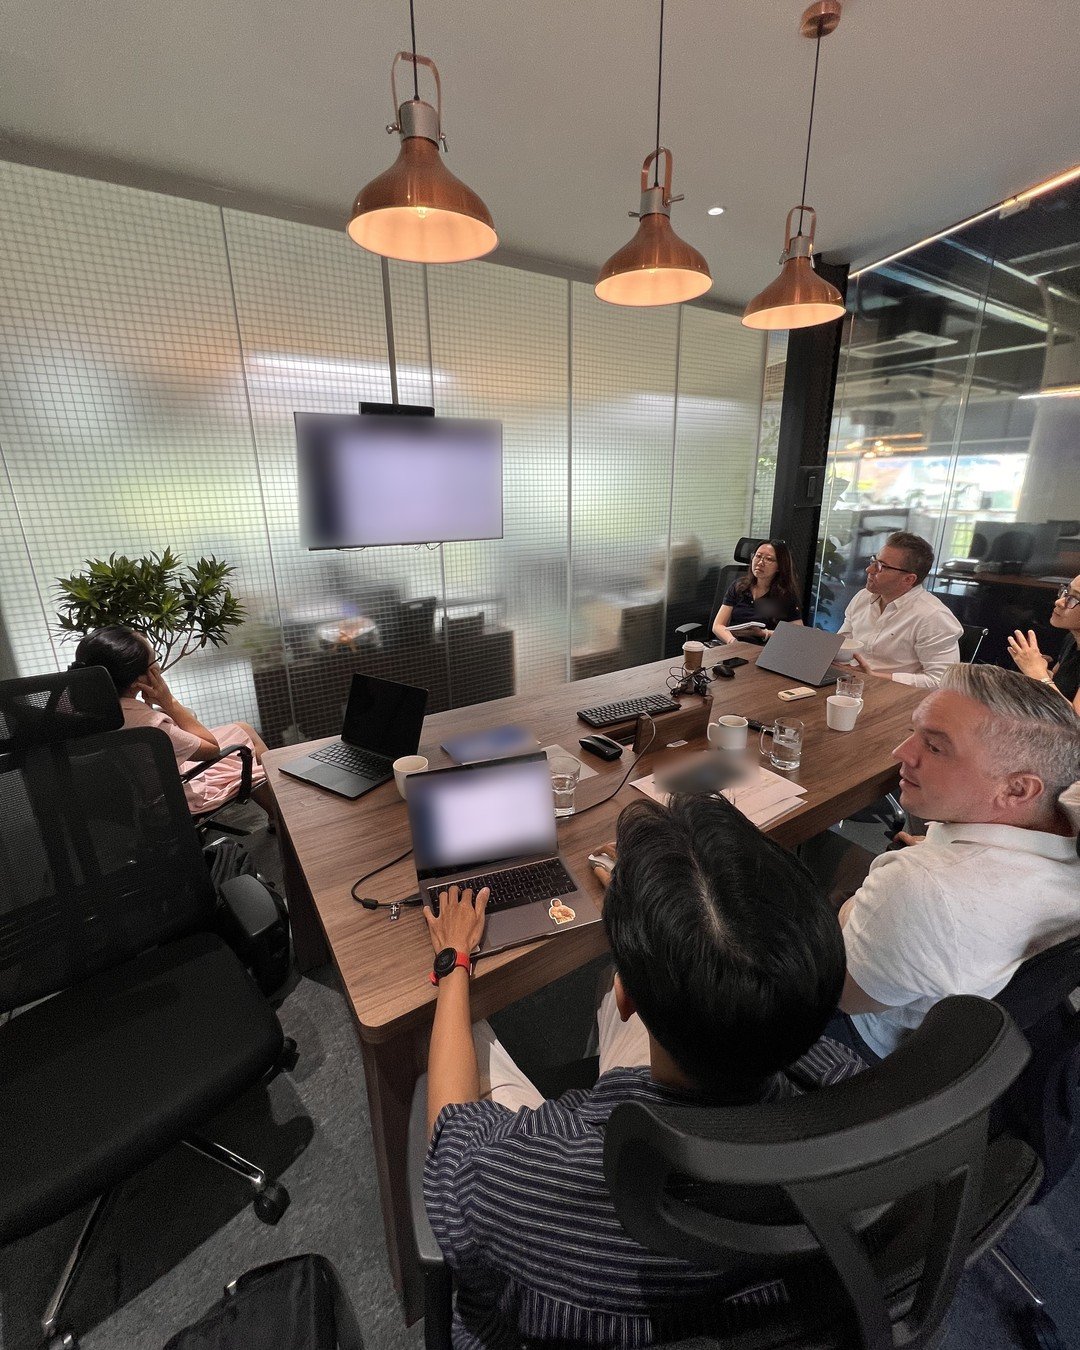
Last week our team demoed a system we have been building with a client's operations team since March (pictured, screens blurred for obvious reasons). It reads their shared inbox, pulls every request into structured data, checks what is missing, drafts the chase and routes the work to the right person. A person approves every email that goes out.
I co-founded Saigon Digital, and we have spent most of this year building systems like that one, for clients and for ourselves. This post is how we do it: the five steps we follow, what it looks like in a real business, and how the same model runs inside our own agency.
What is AI implementation, really?
AI implementation means changing how a process runs. Buying a licence is adoption, which is a different thing.
A chat assistant such as ChatGPT, Gemini or Microsoft Copilot helps one person write, summarise or search faster. That is useful, and most teams should have one. But the process around that person stays exactly as it was: the same inbox, the same hand-offs, the same copy and paste between systems.
An implementation puts AI inside the process as a component. It receives the work, does one defined step, hands a checked result to the next step or to a person, and leaves a record of what it decided and why.
Three quick tests tell you which one you have:
- Where does the output land? In a system (a CRM, a ticket, a spreadsheet), or in a chat window someone has to copy from?
- Can you explain last Tuesday? If the AI made a wrong call a week ago, can you see what it was given and what it decided?
- Does a fix stay fixed? When someone corrects it, is that correction locked in, or does the same mistake come back next month?
If the answers are "chat window", "no" and "no", you have adopted a tool. Nothing wrong with that. It is just not an implementation, and it will not change how the business runs.
Why do so many AI projects stall?
The most quoted figure on this comes from MIT's NANDA initiative, whose 2025 report found that only around 5% of the enterprise generative AI pilots it studied were producing measurable financial value. Treat that as a signal rather than a law: the sample was small, it relied partly on interviews and self-reporting, and the method has been debated. But it matches what we see.
From our own projects, three reasons come up again and again.
They start with the tool. Someone sees a demo, buys a platform, and then goes looking for a process to put it in. The order should be the other way round.
The model knows nothing about the company. A model knows a great deal about the world and nothing about who approves a discount, which clients always get a phone call, or what your team never says in a proposal. Your people know all of that, and most of it is written down nowhere.
People expect it to learn on the job. It does not. The way we explain it to clients: the AI is a very good new hire who never remembers yesterday. It does not improve by being used. It improves when someone corrects it and says why, and when that correction is turned into a test.
How do we implement AI in a business? Our five steps
The model is step three. Most of the value is decided in steps one and two.
Step 1: Map the work, in the team's words
We start with the people who do the job, not the org chart. These are the questions we actually ask:
- What arrives to start the work, from whom, and in what format?
- What are the steps from receiving it to finishing it, including every approval?
- Where are the bottlenecks and the time drains?
- What does the finished output look like, and who receives it?
- Which tools do you use today?
- If you could fix one thing first, what would it be?
The answers are rarely what the brief said. For the client above, they were about admin: requests arriving incomplete, attachments sent as scanned PDFs when the team needed spreadsheets, and every request going out to as many as 20 suppliers whose replies then had to be compiled by hand.
This is also when you measure the baseline. How long does the step take today, and how often does it go wrong? If you skip this, you will never be able to prove the return later. It is the step clients most want to skip and the one we push hardest on.
Step 2: Build the company brain
Before we build a single agent, we write the business down. We call this the company brain, and it has four layers:
| Layer | What it holds | Example |
|---|---|---|
| DNA | Who you are, what you sell, who you sell to, how you sound | Positioning, ideal client, services, tone of voice |
| Rules | What an agent may do alone, and what needs a person | Approval tiers, escalation, writing rules |
| Data | Where the live records sit | CRM, inbox, finance system (pointers only, never copies) |
| Agents | Small specialists that do the work | A router plus a handful of focused agents |
The brain is not one giant document. It is a set of small cards, each with one job, a one-line summary, an owner and a review date. Every folder has an index. An agent reads the index, loads the two or three cards its task needs, and leaves the rest alone.
That matters more than it sounds. Everything an agent reads before it starts costs money and adds room for confusion. When we modelled this on our own business, the context a six-agent workflow had to read before doing any work fell from about 95,000 tokens to about 31,000. That is an estimate from file sizes, not a benchmark, but the direction is the point: less to read means fewer mistakes and a smaller bill.
Two rules keep the brain honest. Link, do not copy: a fact lives in one card and others point to it. And no live data in cards: contract values, deal stages and contacts stay in the system of record, so nothing goes stale.
The models will change every few months. The brain is the part you keep.
Step 3: Build a pipeline, not a chatbot
A pipeline is a set of checked steps, each doing one job. For an inbox process, that is typically: separate the types of email, classify what is being asked, extract the details, validate them, route the work, and draft a reply.
The design choices that make it reliable:
- Structured output, checked by code. Every AI step returns fields in a fixed shape. If the shape is wrong, the result is rejected, not passed along.
- The right model for each step. A fast, cheap model sorts and classifies. A stronger model reads the difficult documents. We choose by measured results on the client's own cases, not by brand.
- Code where code is enough. If a spreadsheet can be parsed directly, it is. AI reads the scanned PDF only when nothing simpler works.
- No guessing. When the system is not sure, it flags a person. Early on, every time we let a system guess, we got a screenshot of the result. So it does not guess.
- Nothing gets lost. Every email is logged before any AI touches it, so a failure later in the pipeline is visible rather than silent.
Step 4: Keep people in the approval seat
The question is not what AI can do. It is what you will let it do without asking. We set that out as tiers before anything goes live:
| Action | Tier | Who approves |
|---|---|---|
| Research, look up records, analyse | Read | Nobody |
| Create a task, log a note, file a lead | Safe write | Nobody, but logged |
| Emails, proposals, reports | Draft | A person sends |
| Anything a client sees, any price, any contract change | Needs a person | A named owner |
| Payments, deletions, credentials | Blocked | Never exposed to agents |
Our house rule fits in five words: the AI drafts, people send. Every AI decision goes into an audit log, so when someone asks "why did it do that?", there is an answer.
Step 5: Measure, then widen
Before go-live we replay real past cases through the system and score the results. Permissions widen only for the workflows that pass.
After go-live, improvement comes from four places, and only four:
- A person corrects the system and says why.
- A test locks that fix in, so it cannot quietly come back.
- A better instruction, saved as a new version.
- A newer model, checked against the same tests before it replaces the old one.
That is why the five-second feedback box on screen matters more than any demo. For higher-stakes checks we go further: the system cannot show a finding unless it can quote the source document word for word. No quote, no finding.
We track two numbers with a target of zero: made-up facts, and approvals that were bypassed.
What does AI implementation look like in a real business?
Back to the client in the photo. Their operations team runs on a shared inbox. Every piece of work arrives as an email, and before the system existed, a skilled person had to do the following for every one:
| Before | After |
|---|---|
| Someone reads each email when they get to it | Every email is picked up within five minutes |
| Supplier replies and new requests mixed together | Supplier replies are separated and matched to the right job |
| Details re-typed from the email and attachments | Details pulled into structured fields, attachments read, scanned PDFs included |
| Missing information spotted by eye, chased by hand | Gaps checked automatically, the chase drafted for a person to send |
| Work handed out by whoever is free | Routed to the right person, skipping anyone on leave or at capacity |
A person still approves every email that goes out, and every AI decision is logged.
We are not publishing a time-saved figure. The honest version of the return is this: the team now starts each job at the decision, not the inbox. Their expertise goes into the part a customer actually pays for, rather than into re-typing.
The next phase is higher stakes: checking a final contract against what was agreed in negotiation. That is a different class of risk from anything before it, so it is designed to report what it checked, what matched, what differs and what it could not verify, and never to say "all clear". A person ticks every finding before anything is signed off.
How does Saigon Digital use AI inside its own business?
We ran this on ourselves before we built it for anyone else. We did not want to sell a client something we had not lived with.
This is what already runs on agents at Saigon Digital, every day:
- Tasks. The team drops a task into a Google Chat space. A bot reads it, files it in our project system with a deadline and replies in the thread.
- Social. Our LinkedIn posts are drafted, checked and scheduled by a system that cannot publish anything until a person approves it.
- Sales. When a prospect replies, an agent researches them, builds their AI visibility audit and drafts the reply. A person sends it.
- Records. Our project system exposes 33 actions to agents. 23 can only read. 10 can write safe things, such as creating a task. None can send anything to a client, change a price or touch money.
Next, we are moving the whole agency onto the card-based company brain described above: one set of DNA, rules and playbooks that every agent and every person on the team works from, with a router and a small set of specialist agents for growth, delivery, search, build, finance and reporting. All of them start in draft-only mode. Each earns wider permissions by passing replayed real cases first.
In the spirit of the post: this article was drafted with help from the same tools, then checked and edited by me.
Copilot, ChatGPT Enterprise or a custom build?
All three have a place. The question is what you are trying to change.
- For individual productivity, a chat assistant is the right answer. Give your team one, set some rules, and let people get faster at their own work.
- For a process, especially one that is high volume, text heavy and rule bound, an assistant hits a ceiling. It returns prose, it cannot be held to a fixed output, and when it is wrong you cannot show why. That is when a pipeline earns its cost.
- If the concern is where your data lives, that is solvable without giving up a proper build. The same leading models can run inside the cloud platform you already use, such as AWS, Google Cloud or Microsoft Azure, under your existing agreements.
Where does AI implementation pay back first?
The best first candidates share five traits:
- The work arrives as text: emails, forms, documents, tickets.
- It is high volume and repetitive.
- The rules are clear, even if nobody has written them down yet.
- Delay costs something: a slower quote, a missed renewal, an unhappy client.
- A person checks the result anyway, so a human approval step costs little.
Inbound enquiries, document checks, reporting, routing and first drafts of replies usually tick all five. Negotiation, relationships and genuine judgement calls do not. Keep people there, and give them back the hours to do more of it.
If you want examples closer to the front of the business, our guides to AI sales automation workflows and using AI for data analysis cover the most common starting points.
What should you do first?
Not a platform purchase, and not a company-wide rollout. Pick one process.
Write down how it actually runs today, in the words of the people who do it. Measure how long it takes and how often it goes wrong. Then decide whether it is worth building around.
If you would like a second pair of eyes on that, it is exactly what our digital consulting work covers, and our web apps and custom software team builds what comes out of it. Or talk to us directly.
Frequently asked questions
How long does an AI implementation take?
It depends on the process, so we scope in phases. Each phase ends in something the team actually uses, and a phase does not widen until its tests pass. A single process is a matter of months, not years. The client project above started in March 2026 and went live in stages.
Will AI replace our team?
Not in the systems we build. Every design keeps a person approving anything a client sees and anything that touches money. The aim is to give skilled people back the hours they spend on admin, so they can spend them on the work customers pay for.
Is our data safe?
It has to be, or the project does not happen. We fix data retention terms with the AI provider in writing before sensitive documents are involved, keep live records in your own systems rather than copying them into prompts, and can run the models inside your existing cloud tenancy if your IT team requires it. Speed and AI never excuse a security gap.
Do we need to replace our existing systems?
Usually not. We build around what you already have, such as your email, CRM and spreadsheets, through their APIs. The client example above runs on top of the shared mailbox the team already used.
Which AI models do you use?
We choose per task, by measured results on your own cases. Much of our current work runs on Anthropic's Claude, with a fast model for sorting and a stronger model for reading, and every model change is checked against the same tests before it goes live.
What does an AI implementation cost?
It depends on the process and how many systems it touches. We scope every project after a discovery conversation, and we would rather tell you a process is not worth automating than build something that will not pay back.
Want to be the brand AI engines recommend?
We make businesses visible on Google and inside AI answers, measured in leads, not vanity metrics.